Chandhan Saai Katuri Applied AI engineer San Francisco Open to new roles
The model is one component. I build the system around it, and the proof that it works.
Vision-model pipelines, agents and evaluation, and the platforms and infrastructure that put them in production.
Proof prints Frames 01 to 04, each the page's own demo All projects
-
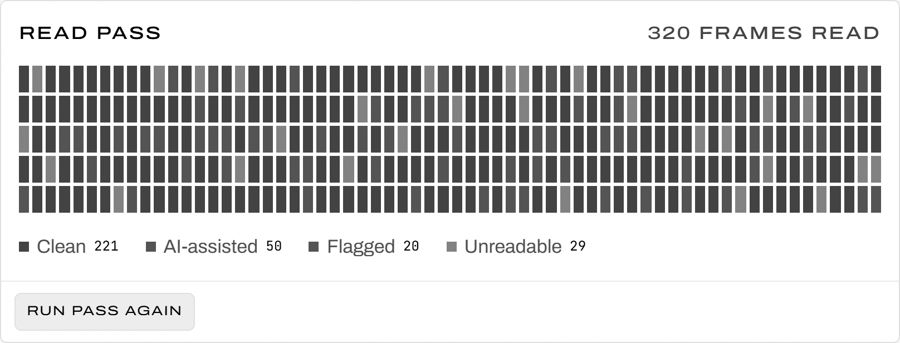 80% precision and recall, 264 sessions
Vision-LLM audit pipeline and annotation platform
A vision-LLM audit pipeline that seals recomputable ledgers, the core of an LLM annotation platform, an LLM-judge verifier, and SOC 2 Type II in a live audit. My work at Verita AI, with the bugs found on the way. Case study -
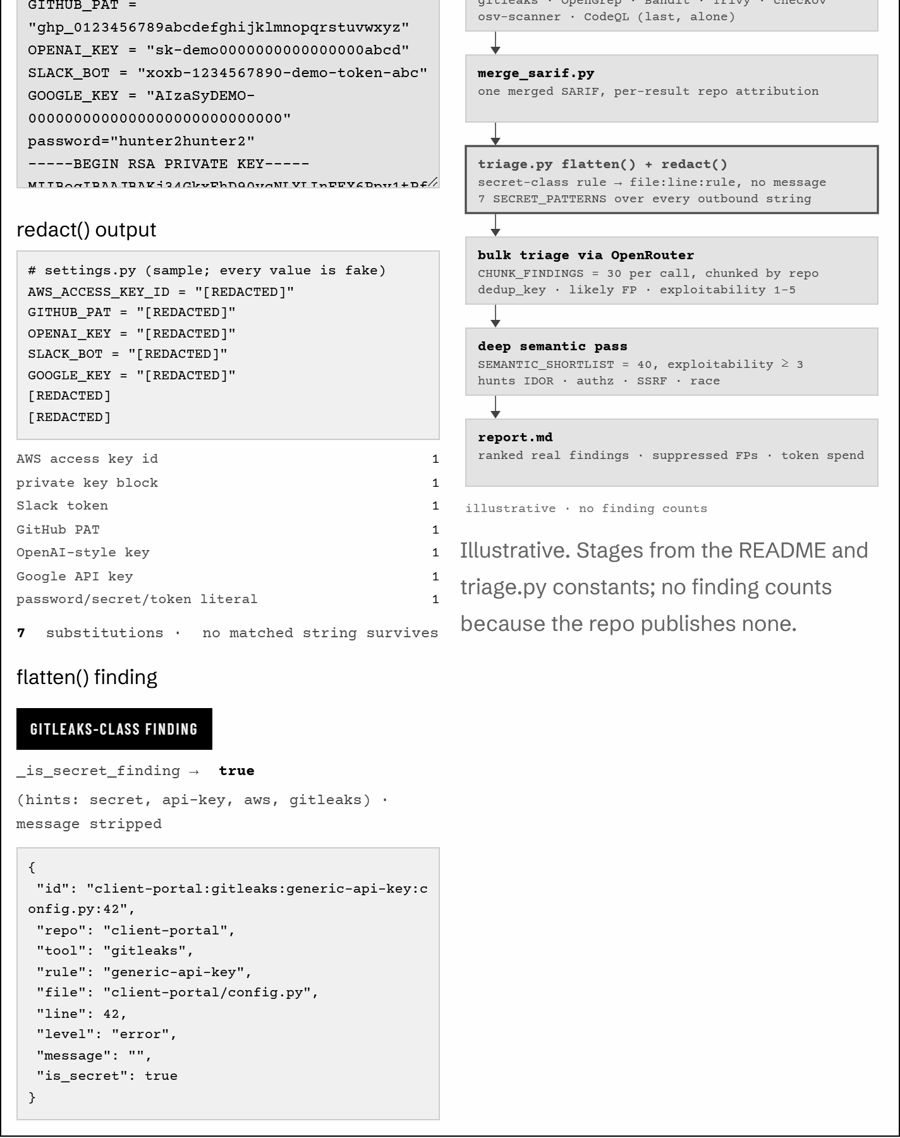 7 scanners, one SARIF, no secret shown to the model
Multi-scanner security audit with LLM triage
Seven pinned scanners on a self-terminating EC2 box, merged to one SARIF and triaged by a reasoning model that is never shown a secret. Case study -
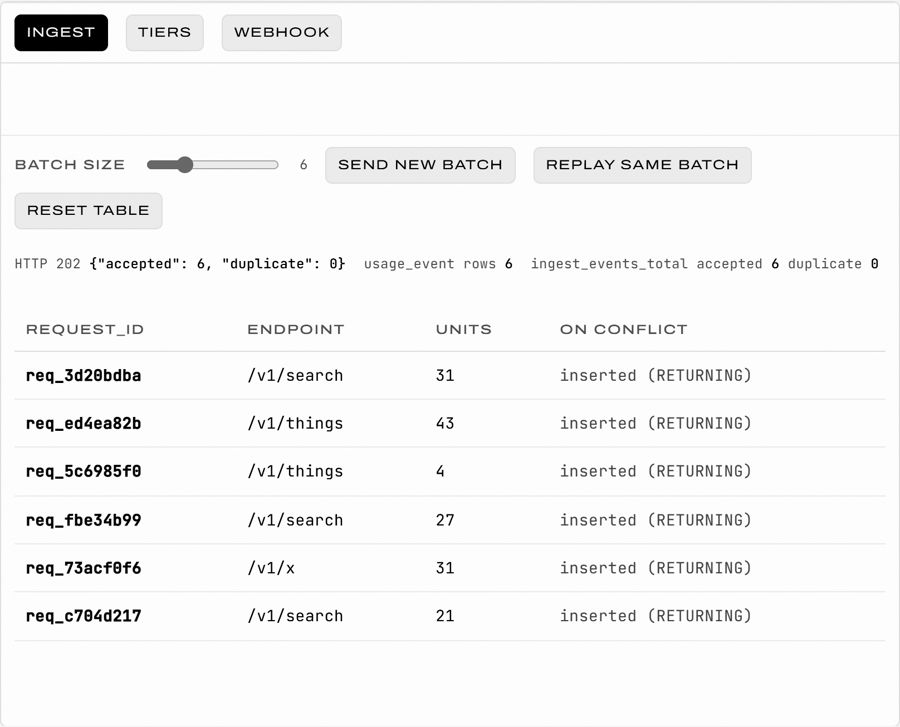 145 tests on live Postgres
Metered API Billing
Usage-based billing where every must-never-happen is a Postgres constraint: idempotent ingest, integer-cent tiers, HMAC webhooks, 145 tests on live Postgres. Case study -
 n = 20, reported with its n
Project D3
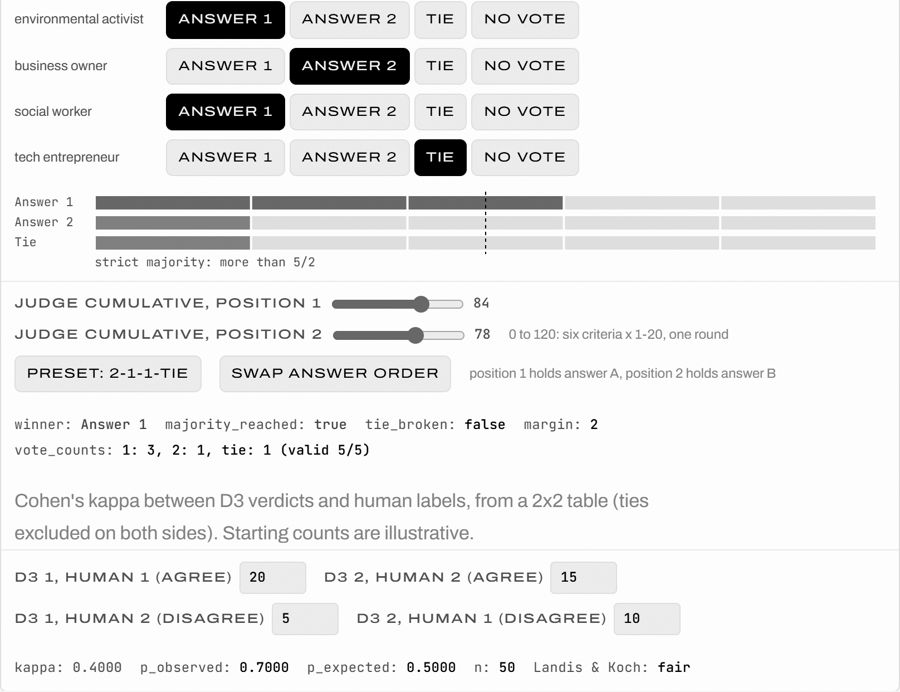
A D3 debate-judge reimplementation: every agent call carries a success flag, juror votes are range-checked and retried, and a verdict needs a strict majority. Case study
What I build
Vision-LLM pipelines, RAG and vector search, LLM-as-judge, and the evaluation that decides what ships: read models benchmarked on golden sets, frontier image models scored against calibrated rubrics, OpenAI, Anthropic and OpenRouter APIs in production.
Multi-agent systems and the products around models: advocate, judge and jury agents in Project D3; a Playwright agent that documents its own runs; the core of an annotation platform with five roles and an append-only audit log; Django, DRF and React end to end.
What keeps it running: tests that genuinely fail, alerting that fires, migrations that roll back, SOC 2 controls proven working, AWS and Terraform, and security tooling with LLM-assisted triage.
Experience
-
Apr 2026 to presentSan Francisco, CA
Verita AI Software Engineer
- Designed and shipped a production vision-LLM audit pipeline: 80% precision and recall on a golden evaluation set, 264 sessions sealed in production, read models benchmarked across providers before one was chosen.
- Built the core of an LLM data-annotation platform in Django REST Framework and React: five-role access control, an audited workflow state machine, an append-only audit log across 54 endpoints, and a test suite grown from 210 to 1,239.
-
Sep 2025 to May 2026Remote
Handshake AI AI Data and Evaluation
- Evaluated frontier image-generation models against calibrated quality rubrics (rendering artifacts, anatomical consistency) to produce preference data for RLHF pipelines.
- Jul 2023 to May 2025 University of Maryland, College Park Master of Engineering, Robotics Perception, planning, control and reinforcement learning. The project work lives on the robotics page.
- Jul 2019 to Jun 2023 SRM Institute of Science and Technology B.Tech, Mechatronics, robotics specialization Control systems, embedded systems, sensors and signal conditioning.
Contact
Email me GitHub LinkedIn Résumé (PDF)
Based in San Francisco, where it is --:--:--. Press / to search this site.